Interview Michael J. A. Berry Data Miners, Inc

Here is an interview with noted Data Mining practitioner Michael Berry, author of seminal books in data mining, noted trainer and consultantmjab picture

Ajay- Your famous book “Data Mining Techniques: For Marketing, Sales, and Customer Relationship Management” came out in 2004, and an update is being planned for 2011. What are the various new data mining techniques and their application that you intend to talk about in that book.

Michael- Each time we do a revision, it feels like writing a whole new book. The first edition came out in 1997 and it is hard to believe how much the world has changed since then. I’m currently spending most of my time in the on-line retailing world. The things I worry about today–improving recommendations for cross-sell and up-sell,and search engine optimization–wouldn’t have even made sense to me back then. And the data sizes that are routine today were beyond the capacity of the most powerful super computers of the nineties. But, if possible, Gordon and I have changed even more than the data mining landscape. What has changed us is experience. We learned an awful lot between the first and second editions, and I think we’ve learned even more between the second and third.

One consequence is that we now have to discipline ourselves to avoid making the book too heavy to lift. For the first edition, we could write everything we knew (and arguably, a bit more!); now we have to remind ourselves that our intended audience is still the same–intelligent laymen with a practical interest in getting more information out of data. Not statisticians. Not computer scientists. Not academic researchers. Although we welcome all readers, we are primarily writing for someone who works in a marketing department and has a title with the word “analyst” or “analytics” in it. We have relaxed our “no equations” rule slightly for cases when the equations really do make things easier to explain, but the core explanations are still in words and pictures.

The third edition completes a transition that was already happening in the second edition. We have fully embraced standard statistical modeling techniques as full-fledged components of the data miner’s toolkit. In the first edition, it seemed important to make a distinction between old, dull, statistics, and new, cool, data mining. By the second edition, we realized that didn’t really make sense, but remnants of that attitude persisted. The third edition rectifies this. There is a chapter on statistical modeling techniques that explains linear and logistic regression, naive Bayes models, and more. There is also a brand new chapter on text mining, a curious omission from previous editions.

There is also a lot more material on data preparation. Three whole chapters are devoted to various aspects of data preparation. The first focuses on creating customer signatures. The second is focused on using derived variables to bring information to the surface, and the third deals with data reduction techniques such as principal components. Since this is where we spend the greatest part of our time in our work, it seemed important to spend more time on these subjects in the book as well.

Some of the chapters have been beefed up a bit. The neural network chapter now includes radial basis functions in addition to multi-layer perceptrons. The clustering chapter has been split into two chapters to accommodate new material on soft clustering, self-organizing maps, and more. The survival analysis chapter is much improved and includes material on some of our recent application of survival analysis methods to forecasting. The genetic algorithms chapter now includes a discussion of swarm intelligence.

Ajay- Describe your early career and how you came into Data Mining as a profession. What do you think of various universities now offering MS in Analytics. How do you balance your own teaching experience with your consulting projects at The Data Miners.

Michael- I fell into data mining quite by accident. I guess I always had a latent interest in the topic. As a high school and college student, I was a fan of Martin Gardner‘s mathematical games in in Scientific American. One of my favorite things he wrote about was a game called New Eleusis in which one players, God, makes up a rule to govern how cards can be played (“an even card must be followed by a red card”, say) and the other players have to figure out the rule by watching what plays are allowed by God and which ones are rejected. Just for my own amusement, I wrote a computer program to play the game and presented it at the IJCAI conference in, I think, 1981.

That paper became a chapter in a book on computer game playing–so my first book was about finding patterns in data. Aside from that, my interest in finding patterns in data lay dormant for years. At Thinking Machines, I was in the compiler group. In particular, I was responsible for the run-time system of the first Fortran Compiler for the CM-2 and I represented Thinking Machines at the Fortran 8X (later Fortran-90) standards meetings.

What changed my direction was that Thinking Machines got an export license to sell our first machine overseas. The machine went to a research lab just outside of Paris. The connection machine was so hard to program, that if you bought one, you got an applications engineer to go along with it. None of the applications engineers wanted to go live in Paris for a few months, but I did.

Paris was a lot of fun, and so, I discovered, was actually working on applications. When I came back to the states, I stuck with that applied focus and my next assignment was to spend a couple of years at Epsilon, (then a subsidiary of American Express) working on a database marketing system that stored all the “records of charge” for American Express card members. The purpose of the system was to pick ads to go in the billing envelope. I also worked on some more general purpose data mining software for the CM-5.

When Thinking Machines folded, I had the opportunity to open a Cambridge office for a Virginia-based consulting company called MRJ that had been a major channel for placing Connection Machines in various government agencies. The new group at MRJ was focused on data mining applications in the commercial market. At least, that was the idea. It turned out that they were more interested in data warehousing projects, so after a while we parted company.

That led to the formation of Data Miners. My two partners in Data Miners, Gordon Linoff and Brij Masand, share the Thinking Machines background.

To tell the truth, I really don’t know much about the university programs in data mining that have started to crop up. I’ve visited the one at NC State, but not any of the others.

I myself teach a class in “Marketing Analytics” at the Carroll School of Management at Boston College. It is an elective part of the MBA program there. I also teach short classes for corporations on their sites and at various conferences.

Ajay- At the previous Predictive Analytics World, you took a session on Forecasting and Predicting Subsciber levels (http://www.predictiveanalyticsworld.com/dc/2009/agenda.php#day2-6) .

It seems inability to forecast is a problem many many companies face today. What do you think are the top 5 principles of business forecasting which companies need to follow.

Michael- I don’t think I can come up with five. Our approach to forecasting is essentially simulation. We try to model the underlying processes and then turn the crank to see what happens. If there is a principal behind that, I guess it is to approach a forecast from the bottom up rather than treating aggregate numbers as a time series.

Ajay- You often partner your talks with SAS Institute, and your blog at http://blog.data-miners.com/ sometimes contain SAS code as well. What particular features of the SAS software do you like. Do you use just the Enterprise Miner or other modules as well for Survival Analysis or Forecasting.

Michael- Our first data mining class used SGI’s Mineset for the hands-on examples. Later we developed versions using Clementine, Quadstone, and SAS Enterprise Miner. Then, market forces took hold. We don’t market our classes ourselves, we depend on others to market them and then share in the revenue.

SAS turned out to be much better at marketing our classes than the other companies, so over time we stopped updating the other versions. An odd thing about our relationship with SAS is that it is only with the education group. They let us use Enterprise Miner to develop course materials, but we are explicitly forbidden to use it in our consulting work. As a consequence, we don’t use it much outside of the classroom.

Ajay- Also any other software you use (apart from SQL and J)

Michael- We try to fit in with whatever environment our client has set up. That almost always is SQL-based (Teradata, Oracle, SQL Server, . . .). Often SAS Stat is also available and sometimes Enterprise Miner.

We run into SPSS, Statistica, Angoss, and other tools as well. We tend to work in big data environments so we’ve also had occasion to use Ab Initio and, more recently, Hadoop. I expect to be seeing more of that.

Biography-

Together with his colleague, Gordon Linoff, Michael Berry is author of some of the most widely read and respected books on data mining. These best sellers in the field have been translated into many languages. Michael is an active practitioner of data mining. His books reflect many years of practical, hands-on experience down in the data mines.

Data Mining Techniques cover

Data Mining Techniques for Marketing, Sales and Customer Relationship Management

by Michael J. A. Berry and Gordon S. Linoff
copyright 2004 by John Wiley & Sons
ISB

Mining the Web cover

Mining the Web

by Michael J.A. Berry and Gordon S. Linoff
copyright 2002 by John Wiley & Sons
ISBN 0-471-41609-6

Non-English editions available in Traditional Chinese and Simplified Chinese

This book looks at the new opportunities and challenges for data mining that have been created by the web. The book demonstrates how to apply data mining to specific types of online businesses, such as auction sites, B2B trading exchanges, click-and-mortar retailers, subscription sites, and online retailers of digital content.

Mastering Data Mining

by Michael J.A. Berry and Gordon S. Linoff
copyright 2000 by John Wiley & Sons
ISBN 0-471-33123-6

Non-English editions available in Japanese , Italian , Traditional Chinese , and Simplified Chinese

A case study-based guide to applying data mining techniques for solving practical business problems. These “warts and all” case studies are drawn directly from consulting engagements performed by the authors.

A data mining educator as well as a consultant, Michael is in demand as a keynote speaker and seminar leader in the area of data mining generally and the application of data mining to customer relationship management in particular.

Prior to founding Data Miners in December, 1997, Michael spent 8 years at Thinking Machines Corporation. There he specialized in the application of massively parallel supercomputing techniques to business and marketing applications, including one of the largest database marketing systems of the time.
Sector/ Sphere – Faster than Hadoop/Mapreduce at Terasort

Here is a preview of a relatively young software Sector and Sphere- which are claimed to be better than Hadoop /MapReduce at TeraSort Benchmark among others.

http://sector.sourceforge.net/tech.html

System Overview

The Sector/Sphere stack consists of the Sector distributed file system and the Sphere parallel data processing framework. The objective is to support highly effective and efficient large data storage and processing over commodity computer clusters.

Sector/Sphere Architecture

Sector consists of 4 parts, as shown in the above diagram. The Security server maintains the system security configurations such as user accounts, data IO permissions, and IP access control lists. The master servers maintain file system metadata, schedule jobs, and respond users’ requests. Sector supports multiple active masters that can join and leave at run time and they all actively respond users’ requests. The slave nodes are racks of computers that store and process data. The slaves nodes can be located within a single data center to across multiple data centers with high speed network connections. Finally, the client includes tools and programming APIs to access and process Sector data.

Sphere: Parallel Data Processing Framework

Sphere allows developers to write parallel data processing applications with a very simple set of API. It applies user-defined functions (UDF) on all input data segments in parallel. In a Sphere application, both inputs and outputs are Sector files. Multiple Sphere processing can be combined to support more complicated applications, with inputs/outputs exchanged/shared via the Sector file system.

Data segments are processed at their storage locations whenever possible (data locality). Failed data segments may be restarted on other nodes to achieve fault tolerance.

The Sphere framework can be compared to MapReduce as they both enforce data locality and provide simplified programming interfaces. In fact, Sphere can simulate any MapReduce operations, but Sphere is more efficient and flexible. Sphere can provide better data locality for applications that process files or multiple files as minimum input units and for applications that involve with iterative/combinative processing, which requires coordination of multiple UDFs to obtain the final result.

A Sphere application includes two parts: the client program that organizes inputs (including certain parameters), outputs, and UDFs; and the UDFs that process data segments. Data segmentation, load balancing, and fault tolerance are transparent to developers.

Space: Column-based Distbuted Data Table

Space stores data tables in Sector and uses Sphere for parallel query processing. Space is similar to BigTable. Table is stored by columns and is segmented on to multiple slave nodes. Tables are independent and no relationship between tables are supported. A reduced set of SQL operations is supported, including but not limited to table creation and modification, key-value update and lookup, and select operations based on UDF.

Supported by the Sector data placement mechanism and the Sphere parallel processing framework, Space can support efficient key-value lookup and certain SQL queries on very large data tables.

Space is currently still in development.

and just when you thought Hadoop was the only way to be on the cloud.

http://sector.sourceforge.net/benchmark.html

The Terasort Benchmark

The table below lists the performance (total processing time in seconds) of the Terasort benchmark of both Sphere and Hadoop. (Terasort benchmark: suppose there are N nodes in the system, the benchmark generates a 10GB file on each node and sorts the total N*10GB data. Data generation time is excluded.) Note that it is normal to see a longer processing time for more nodes because the total amount of data also increases proportionally.

The performance value listed in this page was achieved using the Open Cloud Testbed. Currently the testbed consists of 4 racks. Each rack has 32 nodes, including 1 NFS server, 1 head node, and 30 compute/slave nodes. The head node is a Dell 1950, dual dual-core Xeon 3.0GHz, 16GB RAM. The compute nodes are Dell 1435s, single dual core AMD Opteron 2.0GHz, 4GB RAM, and 1TB single disk. The 4 racks are located in JHU (Baltimore), StarLight (Chicago), UIC (Chicago), and Calit2(San Diego). The inter-rack bandwidth is 10GE, supported by CiscoWave deployed over National Lambda Rail.

Sphere
Hadoop (3 replicas)
Hadoop (1 replica)
UIC
1265 2889 2252
UIC + StarLight
1361 2896 2617
UIC + StarLight + Calit2
1430 4341 3069
UIC + StarLight + Calit2 + JHU
1526 6675 3702

The benchmark uses the testfs/testdc examples of Sphere and randomwriter/sort examples of Hadoop. Hadoop parameters were tuned to reach good results.

Updated on Sep. 22, 2009: We have benchmarked the most recent versions of Sector/Sphere (1.24a) and Hadoop (0.20.1) on a new set of servers. Each server node costs $2,200 and consits of a single Intel Xeon E5410 2.4GHz CPU, 16GB RAM, 4*1TB RAID0 disk, and 1Gb/s NIC. The 120 nodes are hosted on 4 racks within the same data center and the inter-rack bandwidth is 20Gb/s.

The table below lists the performance of sorting 1TB data using Sector/Sphere version 1.24a and Hadoop 0.20.1. Related Hadoop parameters have been tuned for better performance (e.g., big block size), while Sector/Sphere does not require tuning. In addition, to achieve the highest performance, replication is disabled in both systems (note that replication does not afftect the performance of Sphere but will significantly decrease the performance of Hadoop).

Number of Racks
Sphere
Hadoop
1
28m 25s 85m 49s
2
15m 20s 37m 0s
3
10m 19s 25m 14s
4
7m 56s 17m 45s

AsterData gets $30 mill in funding

From the press release, the maker of Map Reduce based BI software gets 30 mill $ as Series C funding. Given the valuation recently by IBM to Netezza, AsterData seems set to cross the Billion Dollar valuation within the next 18-24 months IMO

Aster Data Closes $30 Million Series C Financing

Explosive Growth and Market Leadership Attracts New and Existing Investors

San Carlos, CA – September 22, 2010 – Aster Data, a market leader in big data management and advanced analytics, today announced that it has closed a $30 million Series C round of financing led by both new and existing investors. The company will use the new funding to accelerate growth, scale operations, and expand its global market share in the $20 billion database market – a market that is experiencing rapid growth as a result of both the explosion in data volumes across organizations and the urgent need to deliver a new class of analytics and data-driven applications. The Series C round of funding includes previous investors Sequoia Capital, JAFCO Ventures, Institutional Venture Partners, Cambrian Ventures, as well as an additional new strategic investor.  Also investing in this round is early investor David Cheriton, who previously backed high-growth companies including Google and VMware, and co-founded several successful technology companies.

Today’s Series C funding announcement underscores a year of strong innovation, execution, and overall momentum for the analytic database company. Key milestones include:

Strong sales growth: Since 2008, Aster Data has doubled revenue year-over-year and secured key customers that leverage Aster Data’s platform to address the big data management problem including MySpace, comScore, Barnes & Noble, and Akamai. Like so many organizations today,
Aster Data’s customers are experiencing explosive data growth across their organizations and recognize the need for rich, advanced analytics that give them deeper insights from their data.

Key executive hires: Quentin Gallivan, former CEO of both PivotLink and Postini and EVP of worldwide sales at Verisign, recently joined the company as Chief Executive Officer. In addition, earlier this year, John Calonico, previously at Interwoven, BEA, and Autodesk, joined as Chief Financial Officer; and Nitin Donde, formerly an executive at EMC and 3PAR, joined as Executive Vice President Engineering.  The strength and experience of Aster Data’s management team helps further establish a strong operational foundation for growth in 2010 and beyond.

Industry recognition: Aster Data was positioned in the “Visionaries” Quadrant of Gartner, Inc.’s

Data Warehouse Database Management Systems Magic Quadrant, published 2010 *; was recently named 2011 Tech Pioneer by the World Economic Forum; was named “Company to Watch” in the Information Management category of TechWeb’s Intelligent Enterprise 2010 Editors’ Choice Awards; and was awarded the 2010 San Francisco Business Times Technology and Innovation Award in the Best Product and Services Category.

Product Innovation: Aster Data continues to deliver ground-breaking capabilities to address the big data management and advanced analytics market need. Its recent announcement of
Aster Data nCluster 4.6 includes a column data store, making it the first hybrid row and column MPP DBMS with a unified SQL and MapReduce analytic framework for advanced analytics on large data sets. This year, Aster Data also delivered the most extensive library of pre-packaged MapReduce analytics totaling over 1000 functions, to ease and accelerate delivery of highly advanced analytic applications.

Aster Data’s analytic database, also called a ‘Data-Analytics Server’ is specifically designed to enable organizations to cost effectively store and analyze massive volumes of data. Aster Data leverages the power of commodity, general-purpose hardware, to reduce the cost to scale to support large data volumes and uniquely allows analysis of all data ‘in-database’ enabling richer and faster processing of large data sets. Aster Data’s in-database analytics engine uses the power of MapReduce, a parallel processing framework created by Google.

”The funding we received in our Series C round is a strong endorsement of Aster Data’s market leadership position and the high growth potential of the big data market,” said Quentin Gallivan, Chief Executive Officer, Aster Data. “The Aster Data team has executed exceptionally well to-date and I am excited to have the resources to accelerate the growth of the company as we expand our operations and execute aggressively across all fronts.”

Windows Azure vs Amazon EC2 (and Google Storage)

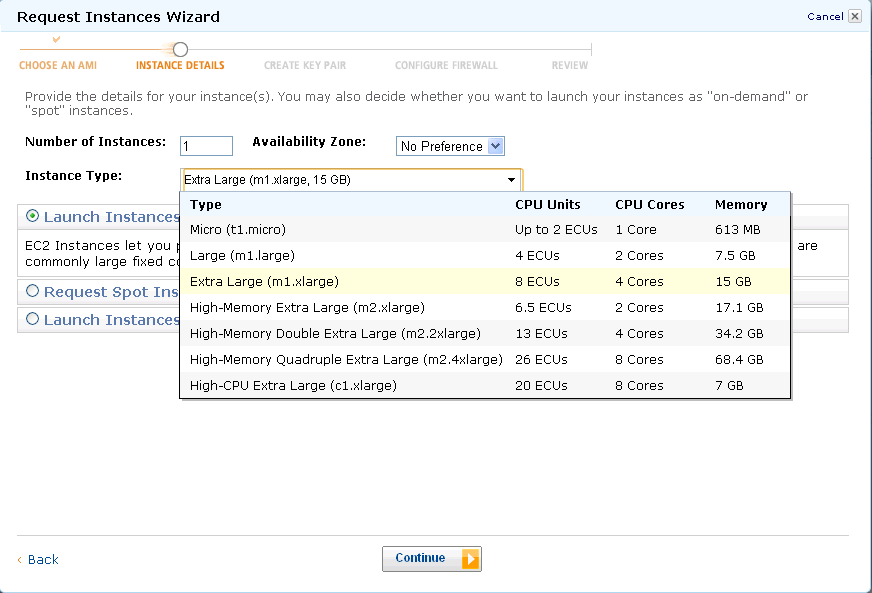
Here is a comparison of Windows Azure instances vs Amazon compute instances

Compute Instance Sizes:

Developers have the ability to choose the size of VMs to run their application based on the applications resource requirements. Windows Azure compute instances come in four unique sizes to enable complex applications and workloads.

Compute Instance Size CPU Memory Instance Storage I/O Performance
Small 1.6 GHz 1.75 GB 225 GB Moderate
Medium 2 x 1.6 GHz 3.5 GB 490 GB High
Large 4 x 1.6 GHz 7 GB 1,000 GB High
Extra large 8 x 1.6 GHz 14 GB 2,040 GB High

Standard Rates:

Windows Azure

  • Compute
    • Small instance (default): $0.12 per hour
    • Medium instance: $0.24 per hour
    • Large instance: $0.48 per hour
    • Extra large instance: $0.96 per hour
  • Storage
    • $0.15 per GB stored per month
    • $0.01 per 10,000 storage transactions
  • Content Delivery Network (CDN)
    • $0.15 per GB for data transfers from European and North American locations*
    • $0.20 per GB for data transfers from other locations*
    • $0.01 per 10,000 transactions*

Source –

http://www.microsoft.com/windowsazure/offers/popup/popup.aspx?lang=en&locale=en-US&offer=MS-AZR-0001P

and

http://www.microsoft.com/windowsazure/windowsazure/

Amazon EC2 has more options though——————————-

http://aws.amazon.com/ec2/pricing/

Standard On-Demand Instances Linux/UNIX Usage Windows Usage
Small (Default) $0.085 per hour $0.12 per hour
Large $0.34 per hour $0.48 per hour
Extra Large $0.68 per hour $0.96 per hour
Micro On-Demand Instances Linux/UNIX Usage Windows Usage
Micro $0.02 per hour $0.03 per hour
High-Memory On-Demand Instances
Extra Large $0.50 per hour $0.62 per hour
Double Extra Large $1.00 per hour $1.24 per hour
Quadruple Extra Large $2.00 per hour $2.48 per hour
High-CPU On-Demand Instances
Medium $0.17 per hour $0.29 per hour
Extra Large $0.68 per hour $1.16 per hour
Cluster Compute Instances
Quadruple Extra Large $1.60 per hour N/A*
* Windows is not currently available for Cluster Compute Instances.

http://aws.amazon.com/ec2/instance-types/

Standard Instances

Instances of this family are well suited for most applications.

Small Instance – default*

1.7 GB memory
1 EC2 Compute Unit (1 virtual core with 1 EC2 Compute Unit)
160 GB instance storage (150 GB plus 10 GB root partition)
32-bit platform
I/O Performance: Moderate
API name: m1.small

Large Instance

7.5 GB memory
4 EC2 Compute Units (2 virtual cores with 2 EC2 Compute Units each)
850 GB instance storage (2×420 GB plus 10 GB root partition)
64-bit platform
I/O Performance: High
API name: m1.large

Extra Large Instance

15 GB memory
8 EC2 Compute Units (4 virtual cores with 2 EC2 Compute Units each)
1,690 GB instance storage (4×420 GB plus 10 GB root partition)
64-bit platform
I/O Performance: High
API name: m1.xlarge

Micro Instances

Instances of this family provide a small amount of consistent CPU resources and allow you to burst CPUcapacity when additional cycles are available. They are well suited for lower throughput applications and web sites that consume significant compute cycles periodically.

Micro Instance

613 MB memory
Up to 2 EC2 Compute Units (for short periodic bursts)
EBS storage only
32-bit or 64-bit platform
I/O Performance: Low
API name: t1.micro

High-Memory Instances

Instances of this family offer large memory sizes for high throughput applications, including database and memory caching applications.

High-Memory Extra Large Instance

17.1 GB of memory
6.5 EC2 Compute Units (2 virtual cores with 3.25 EC2 Compute Units each)
420 GB of instance storage
64-bit platform
I/O Performance: Moderate
API name: m2.xlarge

High-Memory Double Extra Large Instance

34.2 GB of memory
13 EC2 Compute Units (4 virtual cores with 3.25 EC2 Compute Units each)
850 GB of instance storage
64-bit platform
I/O Performance: High
API name: m2.2xlarge

High-Memory Quadruple Extra Large Instance

68.4 GB of memory
26 EC2 Compute Units (8 virtual cores with 3.25 EC2 Compute Units each)
1690 GB of instance storage
64-bit platform
I/O Performance: High
API name: m2.4xlarge

High-CPU Instances

Instances of this family have proportionally more CPU resources than memory (RAM) and are well suited for compute-intensive applications.

High-CPU Medium Instance

1.7 GB of memory
5 EC2 Compute Units (2 virtual cores with 2.5 EC2 Compute Units each)
350 GB of instance storage
32-bit platform
I/O Performance: Moderate
API name: c1.medium

High-CPU Extra Large Instance

7 GB of memory
20 EC2 Compute Units (8 virtual cores with 2.5 EC2 Compute Units each)
1690 GB of instance storage
64-bit platform
I/O Performance: High
API name: c1.xlarge

Cluster Compute Instances

Instances of this family provide proportionally high CPU resources with increased network performance and are well suited for High Performance Compute (HPC) applications and other demanding network-bound applications. Learn more about use of this instance type for HPC applications.

Cluster Compute Quadruple Extra Large Instance

23 GB of memory
33.5 EC2 Compute Units (2 x Intel Xeon X5570, quad-core “Nehalem” architecture)
1690 GB of instance storage
64-bit platform
I/O Performance: Very High (10 Gigabit Ethernet)
API name: cc1.4xlarge

Also http://www.microsoft.com/en-us/sqlazure/default.aspx

offers SQL Databases as a service with a free trial offer

If you are into .Net /SQL big time or too dependent on MS, Azure is a nice option to EC2 http://www.microsoft.com/windowsazure/offers/popup/popup.aspx?lang=en&locale=en-US&offer=COMPARE_PUBLIC

Updated- I just got approved for Google Storage so am adding their info- though they are in Preview (and its free right now) 🙂

https://code.google.com/apis/storage/docs/overview.html

Functionality

Google Storage for Developers offers a rich set of features and capabilities:

Basic Operations

  • Store and access data from anywhere on the Internet.
  • Range-gets for large objects.
  • Manage metadata.

Security and Sharing

  • User authentication using secret keys or Google account.
  • Authenticated downloads from a web browser for Google account holders.
  • Secure access using SSL.
  • Easy, powerful sharing and collaboration via ACLs for individuals and groups.

Performance and scalability

  • Up to 100 gigabytes per object and 1,000 buckets per account during the preview.
  • Strong data consistency—read-after-write consistency for all upload and delete operations.
  • Namespace for your domain—only you can create bucket URIs containing your domain name.
  • Data replicated in multiple data centers across the U.S. and within the same data center.

Tools

  • Web-based storage manager.
  • GSUtil, an open source command line tool.
  • Compatible with many existing cloud storage tools and libraries.

Read the Getting Started Guide to learn more about the service.

Note: Google Storage for Developers does not support Google Apps accounts that use your company domain name at this time.

Back to top

Pricing

Google Storage for Developers pricing is based on usage.

  • Storage—$0.17/gigabyte/month
  • Network
    • Upload data to Google
      • $0.10/gigabyte
    • Download data from Google
      • $0.15/gigabyte for Americas and EMEA
      • $0.30/gigabyte for Asia-Pacific
  • Requests
    • PUT, POST, LIST—$0.01 per 1,000 requests
    • GET, HEAD—$0.01 per 10,000 requests

KXEN Update

Update from a very good data mining software company, KXEN –

  1. Longtime Chairman and founder Roger Haddad is retiring but would be a Board Member. See his interview with Decisionstats here https://decisionstats.wordpress.com/2009/01/05/interview-roger-haddad-founder-of-kxen-automated-modeling-software/ (note images were hidden due to migration from .com to .wordpress.com )
  2. New Members of Leadership are as-
John Ball, CEOJohn Ball
Chief Executive Officer

John Ball brings 20 years of experience in enterprise software, deep expertise in business intelligence and CRM applications, and a proven track record of success driving rapid growth at highly innovative companies.

Prior to joining KXEN, Mr. Ball served in several executive roles at salesforce.com, the leading provider of SaaS applications. Most recently, John served as VP & General Manager, Analytics and Reporting Products, where he spearheaded salesforce.com’s foray into CRM analytics and business intelligence. John also served as VP & General Manager, Service and Support Applications at salesforce.com, where he successfully grew the business to become the second largest and fastest growing product line at salesforce.com. Before salesforce.com, Ball was founder and CEO of Netonomy, the leading provider of customer self-service solutions for the telecommunications industry. Ball also held a number of executive roles at Business Objects, including General Manager, Web Products, where delivered to market the first 3 versions of WebIntelligence. Ball has a master’s degree in electrical engineering from Georgia Tech and a master’s degree in electric

I hope John atleast helps build a KXEN Force.com application- there are only 2 data mining apps there on App Exchange. Also on the wish list  more social media presence, a Web SaaS/Amazon API for KXEN, greater presence in American/Asian conferences, and a solution for SME’s (which cannot afford the premium pricing of the flagship solution. An alliance with bigger BI vendors like Oracle, SAP or IBM  for selling the great social network analysis.

Bill Russell as Non Executive Chairman-

Bill Russell as Non-executive Chairman of the Board, effective July 16 2010. Russell has 30 years of operational experience in enterprise software, with a special focus on business intelligence, analytics, and databases.Russell held a number of senior-level positions in his more than 20 years at Hewlett-Packard, including Vice President and General Manager of the multi-billion dollar Enterprise Systems Group. He has served as Non-executive Chairman of the Board for Sylantro Systems Corporation, webMethods Inc., and Network Physics, Inc. and has served as a board director for Cognos Inc. In addition to KXEN, Russell currently serves on the boards of Saba, PROS Holdings Inc., Global 360, ParAccel Inc., and B.T. Mancini Company.

Xavier Haffreingue as senior vice president, worldwide professional services and solutions.
He has almost 20 years of international enterprise software experience gained in the CRM, BI, Web and database sectors. Haffreingue joins KXEN from software provider Axway where he was VP global support operations. Prior to Axway, he held various leadership roles in the software industry, including VP self service solutions at Comverse Technologies and VP professional services and support at Netonomy, where he successfully delivered multi-million dollar projects across Europe, Asia-Pacific and Africa. Before that he was with Business Objects and Sybase, where he ran support and services in southern Europe managing over 2,500 customers in more than 20 countries.

David Guercio  as senior vice president, Americas field operations. Guercio brings to the role more than 25 years experience of building and managing high-achieving sales teams in the data mining, business intelligence and CRM markets. Guercio comes to KXEN from product lifecycle management vendor Centric Software, where he was EVP sales and client services. Prior to Centric, he was SVP worldwide sales and client services at Inxight Software, where he was also Chairman and CEO of the company’s Federal Systems Group, a subsidiary of Inxight that saw success in the US Federal Government intelligence market. The success in sales growth and penetration into the federal government led to the acquisition of Inxight by Business Objects in 2007, where Guercio then led the Inxight sales organization until Business Objects was acquired by SAP. Guercio was also a key member of the management team and a co-founder at Neovista, an early pioneer in data mining and predictive analytics. Additionally, he held the positions of director of sales and VP of professional services at Metaphor Computer Systems, one of the first data extraction solutions companies, which was acquired by IBM. During his career, Guercio also held executive positions at Resonate and SiGen.

3) Venture Capital funding to fund expansion-

It has closed $8 million in series D funding to further accelerate its growth and international expansion. The round was led by NextStage and included participation from existing investors XAnge Capital, Sofinnova Ventures, Saints Capital and Motorola Ventures.

This was done after John Ball had joined as CEO.

4) Continued kudos from analysts and customers for it’s technical excellence.

KXEN was named a leader in predictive analytics and data mining by Forrester Research (1) and was rated highest for commercial deployments of social network analytics by Frost & Sullivan (2)

Also it became an alliance partner of Accenture- which is also a prominent SAS partner as well.

In Database Optimization-

In KXEN V5.1, a new data manipulation module (ADM) is provided in conjunction with scoring to optimize database workloads and provide full in-database model deployment. Some leading data mining vendors are only now beginning to offer this kind of functionality, and then with only one or two selected databases, giving KXEN a more than five-year head start. Some other vendors are only offering generic SQL generation, not optimized for each database, and do not provide the wealth of possible outputs for their scoring equations: For example, real operational applications require not only to generate scores, but decision probabilities, error bars, individual input contributions – used to derive reasons of decision and more, which are available in KXEN in-database scoring modules.

Since 2005, KXEN has leveraged databases as the data manipulation engine for analytical dataset generation. In 2008, the ADM (Analytical Data Management) module delivered a major enhancement by providing a very easy to use data manipulation environment with unmatched productivity and efficiency. ADM works as a generator of optimized database-specific SQL code and comes with an integrated layer for the management of meta-data for analytics.

KXEN Modeling Factory- (similar to SAS’s recent product Rapid Predictive Modeler http://www.sas.com/resources/product-brief/rapid-predictive-modeler-brief.pdf and http://jtonedm.com/2010/09/02/first-look-rapid-predictive-modeler/)

KXEN Modeling Factory (KMF) has been designed to automate the development and maintenance of predictive analytics-intensive systems, especially systems that include large numbers of models, vast amounts of data or require frequent model refreshes. Information about each project and model is monitored and disseminated to ensure complete management and oversight and to facilitate continual improvement in business performance.

Main Functions

Schedule: creation of the Analytic Data Set (ADS), setup of how and when to score, setup of when and how to perform model retraining and refreshes …

Report
: Monitormodel execution over time, Track changes in model quality over time, see how useful one variable is by considering its multiple instance in models …

Notification
: Rather than having to wade through pages of event logs, KMF Department allows users to manage by exception through notifications.

Other products from KXEN have been covered here before https://decisionstats.wordpress.com/tag/kxen/ , including Structural Risk Minimization- https://decisionstats.wordpress.com/2009/04/27/kxen-automated-regression-modeling/

Thats all for the KXEN update- all the best to the new management team and a splendid job done by Roger Haddad in creating what is France and Europe’s best known data mining company.

Note- Source – http://www.kxen.com


Interview Stephanie McReynolds Director Product Marketing, AsterData

Here is an interview with Stephanie McReynolds who works as as Director of Product Marketing with AsterData. I asked her a couple of questions about the new product releases from AsterData in analytics and MapReduce.

Ajay – How does the new Eclipse Plugin help people who are already working with huge datasets but are new to AsterData’s platform?

Stephanie- Aster Data Developer Express, our new SQL-MapReduce development plug-in for Eclipse, makes MapReduce applications easy to develop. With Aster Data Developer Express, developers can develop, test and deploy a complete SQL-MapReduce application in under an hour. This is a significant increase in productivity over the traditional analytic application development process for Big Data applications, which requires significant time coding applications in low-level code and testing applications on sample data.

Ajay – What are the various analytical functions that are introduced by you recently- list say the top 10.

Stephanie- At Aster Data, we have an intense focus on making the development process easier for SQL-MapReduce applications. Aster Developer Express is a part of this initiative, as is the release of pre-defined analytic functions. We recently launched both a suite of analytic modules and a partnership program dedicated to delivering pre-defined analytic functions for the Aster Data nCluster platform. Pre-defined analytic functions delivered by Aster Data’s engineering team are delivered as modules within the Aster Data Analytic Foundation offering and include analytics in the areas of pattern matching, clustering, statistics, and text analysis– just to name a few areas. Partners like Fuzzy Logix and Cobi Systems are extending this library by delivering industry-focused analytics like Monte Carlo Simulations for Financial Services and geospatial analytics for Public Sector– to give you a few examples.

Ajay – So okay I want to do a K Means Cluster on say a million rows (and say 200 columns) using the Aster method. How do I go about it using the new plug-in as well as your product.

Stephanie- The power of the Aster Data environment for analytic application development is in SQL-MapReduce. SQL is a powerful analytic query standard because it is a declarative language. MapReduce is a powerful programming framework because it can support high performance parallel processing of Big Data and extreme expressiveness, by supporting a wide variety of programming languages, including Java, C/C#/C++, .Net, Python, etc. Aster Data has taken the performance and expressiveness of MapReduce and combined it with the familiar declarativeness of SQL. This unique combination ensures that anyone who knows standard SQL can access advanced analytic functions programmed for Big Data analysis using MapReduce techniques.

kMeans is a good example of an analytic function that we pre-package for developers as part of the Aster Data Analytic Foundation. What does that mean? It means that the MapReduce portion of the development cycle has been completed for you. Each pre-packaged Aster Data function can be called using standard SQL, and executes the defined analytic in a fully parallelized manner in the Aster Data database using MapReduce techniques. The result? High performance analytics with the expressiveness of low-level languages accessed through declarative SQL.

Ajay – I see an an increasing focus on Analytics. Is this part of your product strategy and how do you see yourself competing with pure analytics vendors.

Stephanie – Aster Data is an infrastructure provider. Our core product is a massively parallel processing database called nCluster that performs at or beyond the capabilities of any other analytic database in the market today. We developed our analytics strategy as a response to demand from our customers who were looking beyond the price/performance wars being fought today and wanted support for richer analytics from their database provider. Aster Data analytics are delivered in nCluster to enable analytic applications that are not possible in more traditional database architectures.

Ajay – Name some recent case studies in Analytics of implementation of MR-SQL with Analytical functions

Stephanie – There are three new classes of applications that Aster Data Express and Aster Analytic Foundation support: iterative analytics, prediction and optimization, and ad hoc analysis.

Aster Data customers are uncovering critical business patterns in Big Data by performing hypothesis-driven, iterative analytics. They are exploring interactively massive volumes of data—terabytes to petabytes—in a top-down deductive manner. ComScore, an Aster Data customer that performs website experience analysis is a good example of an Aster Data customer performing this type of analysis.

Other Aster Data customers are building applications for prediction and optimization that discover trends, patterns, and outliers in data sets. Examples of these types of applications are propensity to churn in telecommunications, proactive product and service recommendations in retail, and pricing and retention strategies in financial services. Full Tilt Poker, who is using Aster Data for fraud prevention is a good example of a customer in this space.

The final class of application that I would like to highlight is ad hoc analysis. Examples of ad hoc analysis that can be performed includes social network analysis, advanced click stream analysis, graph analysis, cluster analysis and a wide variety of mathematical, trigonometry, and statistical functions. LinkedIn, whose analysts and data scientists have access to all of their customer data in Aster Data are a good example of a customer using the system in this manner.

While Aster Data customers are using nCluster in a number of other ways, these three new classes of applications are areas in which we are seeing particularly innovative application development.

Biography-

Stephanie McReynolds is Director of Product Marketing at Aster Data, where she is an evangelist for Aster Data’s massively parallel data-analytics server product. Stephanie has over a decade of experience in product management and marketing for business intelligence, data warehouse, and complex event processing products at companies such as Oracle, Peoplesoft, and Business Objects. She holds both a master’s and undergraduate degree from Stanford University.